Job Types
Conscia offers several out of the box Job Types that you can use to instantiate a Job, and optionally, schedule it. Each of these Job Types can be run completely independently of each other, although some have overlapping functionality.
Running Jobs
Any given Job can be set in a Job definition or run directly.
To create a Job definition, use the API detailed here. The Job Type is defined in the jobType property and the specific Input Parameters associated with each Job Type described below are defined in the params object.
To run a Job directly, use the Job Types _execute endpoint detailed here. The jobType is set in the URL path, and the rest of the Input Parameters are defined in the params object. For example,
POST {{engineUrl}}/job-types/exportCollection/_execute
Content-Type: application/json
X-Customer-Code: {{customerCode}}
Authorization: Bearer {{apiKey}}
{
  "params": {
    "collectionCode": "movie",
    "targetBucketCode": "processed",
    "filenamePattern": "movies.jsonl"
  }
}
Import Data Files
| Job Type Code | Description |
|---|---|
| importDataFiles | The Import Data Files job validates Data Files (like the Validates Data Files job) and imports them into a Data Collection. Depending on whether the Data Files were successfully imported, they can be moved to different Buckets. These Buckets are specified in the Job definition. It also provides an option to transform the data before loading it into the Data Collection. |
For more information on how to generally work with data files, please see the documentation here.
Input Parameters
| Parameter | Required | Description |
|---|---|---|
| incomingBucketCode | Yes | The DX Graph Bucket that contains the Data Files specified by Filename Pattern. |
| skippedBucketCode | Yes | A file that has been skipped due to Process Last Matched File is true will be moved here. It will not be validated. |
| processedBucketCode | Yes | A file that is fully imported into a collection with no validation errors is moved here. A file that has any validation errors with Skip Invalid Records is true will be moved here along with the corresponding error files. |
| invalidBucketCode | Yes | This is mandatory if Skip Invalid Records is false. A file that has any validation errors when Skip Invalid Records is false will be moved here along with the corresponding error files. |
| filenamePattern | Yes | Groups files into a set of files to be processed together. e.g. products_*.csv |
| recordIdentifierField | Yes | Indicates which field uniquely identifies the records in the Data Files. Validation errors use this to point out erroneous records. |
| parseOptions | Yes | Configures how to parse the Source Data Files. e.g. Are the files delimited vs Excel vs JSON format? |
| collectionCode | Yes | The Data Collection to import Data Files into |
| sourceSchema | No | The JSON Schema that must be conformed to. |
| targetSchema | No | JSON schema that is applied to the transformed records. Default: uses the schema of specified Collection Code. |
| transformers | No | A list of transformations applied to each validated source record. |
| skipInvalidRecords | No | Default: false. If false, if any validation errors occurred, no data will be imported. |
| processLastMatchedFile | No | Data Files are scanned in alphabetical order so that you are able to use filenames to sequence the processing sequence. If this parameter is set to true, then only the last matching Data File will be processed and the previous files will be skipped. |
| ifExists | No | Options: merge or replace. Default: merge. |
| ifNotExists | No | Options: create, fail, or ignore. Default: create. |
| skipEventEmission | No | When skipEventEmission is set to true any triggers for DataRecordCreated, DataRecordUpdated or DataRecordRemoved for the target Collection will not fire. It is useful (and faster) when performing bulk inserts/updates where you know you do not want to process those triggers. |
To execute this job directly against a Data Bucket:
POST {{engineUrl}}/buckets/{{incomingBucketCode}}/files/_import
Content-Type: application/json
X-Customer-Code: {{customerCode}}
Authorization: Bearer {{apiKey}}
{
  "skippedBucketCode": "skipped",
  "processedBucketCode": "processed",
  "invalidBucketCode": "invalidated",
  "filenamePattern": "articles_*.jsonl",
  "skipInvalidRecords": false,
  "recordIdentifierField": "article_id",
  "collectionCode": "contentful-articles",
  "parseOptions": {
    "format": "JSONL"
  }
}
Validate Data Files
| Job Type Code | Description |
|---|---|
| validateDataFiles | The Validate Data File job ensures that a set of Data Files (specified by a filename pattern) is parseable and conforms to a specified schema. Depending on whether the Data Files were successfully validated, they can be moved to a specified data Bucket. |
Input Parameters
| Parameter | Required | Description |
|---|---|---|
| incomingBucketCode | Yes | The DX Graph Bucket that contains the Data Files specified by Filename Pattern. |
| validatedBucketCode | Yes | If this is specified, successfully validated Data Files are moved to this Bucket. |
| invalidBucketCode | Yes | If this is specified, unsuccessfully validated Data Files are moved to this Bucket. |
| filenamePattern | Yes | Groups files into a set of files to be processed together. e.g. products_*.csv |
| sourceSchema | No | The JSON Schema that must be conformed to. |
| recordIdentifierField | Yes | Indicates which field uniquely identifies the records in the Data Files. Validation errors use this to point out erroneous records. |
| parseOptions | Yes | Configures how to parse the Source Data Files. e.g. Are the files delimited vs Excel vs JSON format? |
| collectionCode | Yes | The Data Collection to import Data Files into |
| transformers | No | A list of transformations applied to each validated source record. |
| targetSchema | No | JSON schema that is applied to the transformed records. Default: uses the schema of specified Collection Code. |
To execute this job directly against a Data Bucket:
POST {{engineUrl}}/buckets/{{incomingBucketCode}}/files/_validate
Content-Type: application/json
X-Customer-Code: {{customerCode}}
Authorization: Bearer {{apiKey}}
{
  "validatedBucketCode": "validated",
  "invalidBucketCode": "invalidated",
  "filenamePattern": "articles_*.jsonl",
  "recordIdentifierField": "article_id",
  "collectionCode": "contentful-articles",
  "parseOptions": {
    "format": "JSONL"
  }
}
Transform Data Files
| Job Type Code | Description |
|---|---|
| transformDataFiles | This job type is used validate (like the Validates Data Files job) and transform Data Files. |
Input Parameters
| Parameter | Required | Description |
|---|---|---|
| sourceBucketCode | Yes | The DX Graph Bucket that contains the Data Files specified by Filename Pattern. |
| targetBucketCode | Yes | A file with no validation errors is moved here or (a file that has validation errors with Skip Invalid Records is true) will be moved here along with the transformed file and any corresponding error files. The transformed files will be JSONL format and will have the filename: {{sourceFilename}}.YYYYMMDD_HHmmss.transformed.jsonl where YYYYMMDD_HHmmss is the timestamp of when the file was generated. |
| invalidBucketCode | Yes | This is mandatory if Skip Invalid Records is false. A file that has any validation errors when Skip Invalid Records is false will be moved here along with the corresponding error files. |
| filenamePattern | Yes | Groups files into a set of files to be processed together. e.g. products_*.csv |
| sourceSchema | No | The JSON Schema that must be conformed to. |
| recordIdentifierField | Yes | Indicates which field uniquely identifies the records in the Data Files. Validation errors use this to point out erroneous records. |
| parseOptions | Yes | Configures how to parse the Source Data Files. e.g. Are the files delimited vs Excel vs JSON format? |
| transformers | No | A list of transformations applied to each validated source record. |
| targetSchema | No | JSON schema that is applied to the transformed records. Default: uses the schema of specified Collection Code. |
| skipInvalidRecords | No | Default: false. If false, if any validation errors occurred, no data will be imported. |
To execute this job directly against a Data Bucket:
POST {{engineUrl}}/buckets/{{incomingBucketCode}}/files/_transform
Content-Type: application/json
X-Customer-Code: {{customerCode}}
Authorization: Bearer {{apiKey}}
{
  "targetBucketCode": "processed",
  "invalidBucketCode": "invalidated",
  "filenamePattern": "articles_*.jsonl",
  "recordIdentifierField": "article_id",
  "collectionCode": "contentful-articles",
  "parseOptions": {
    "format": "JSONL"
  }
}
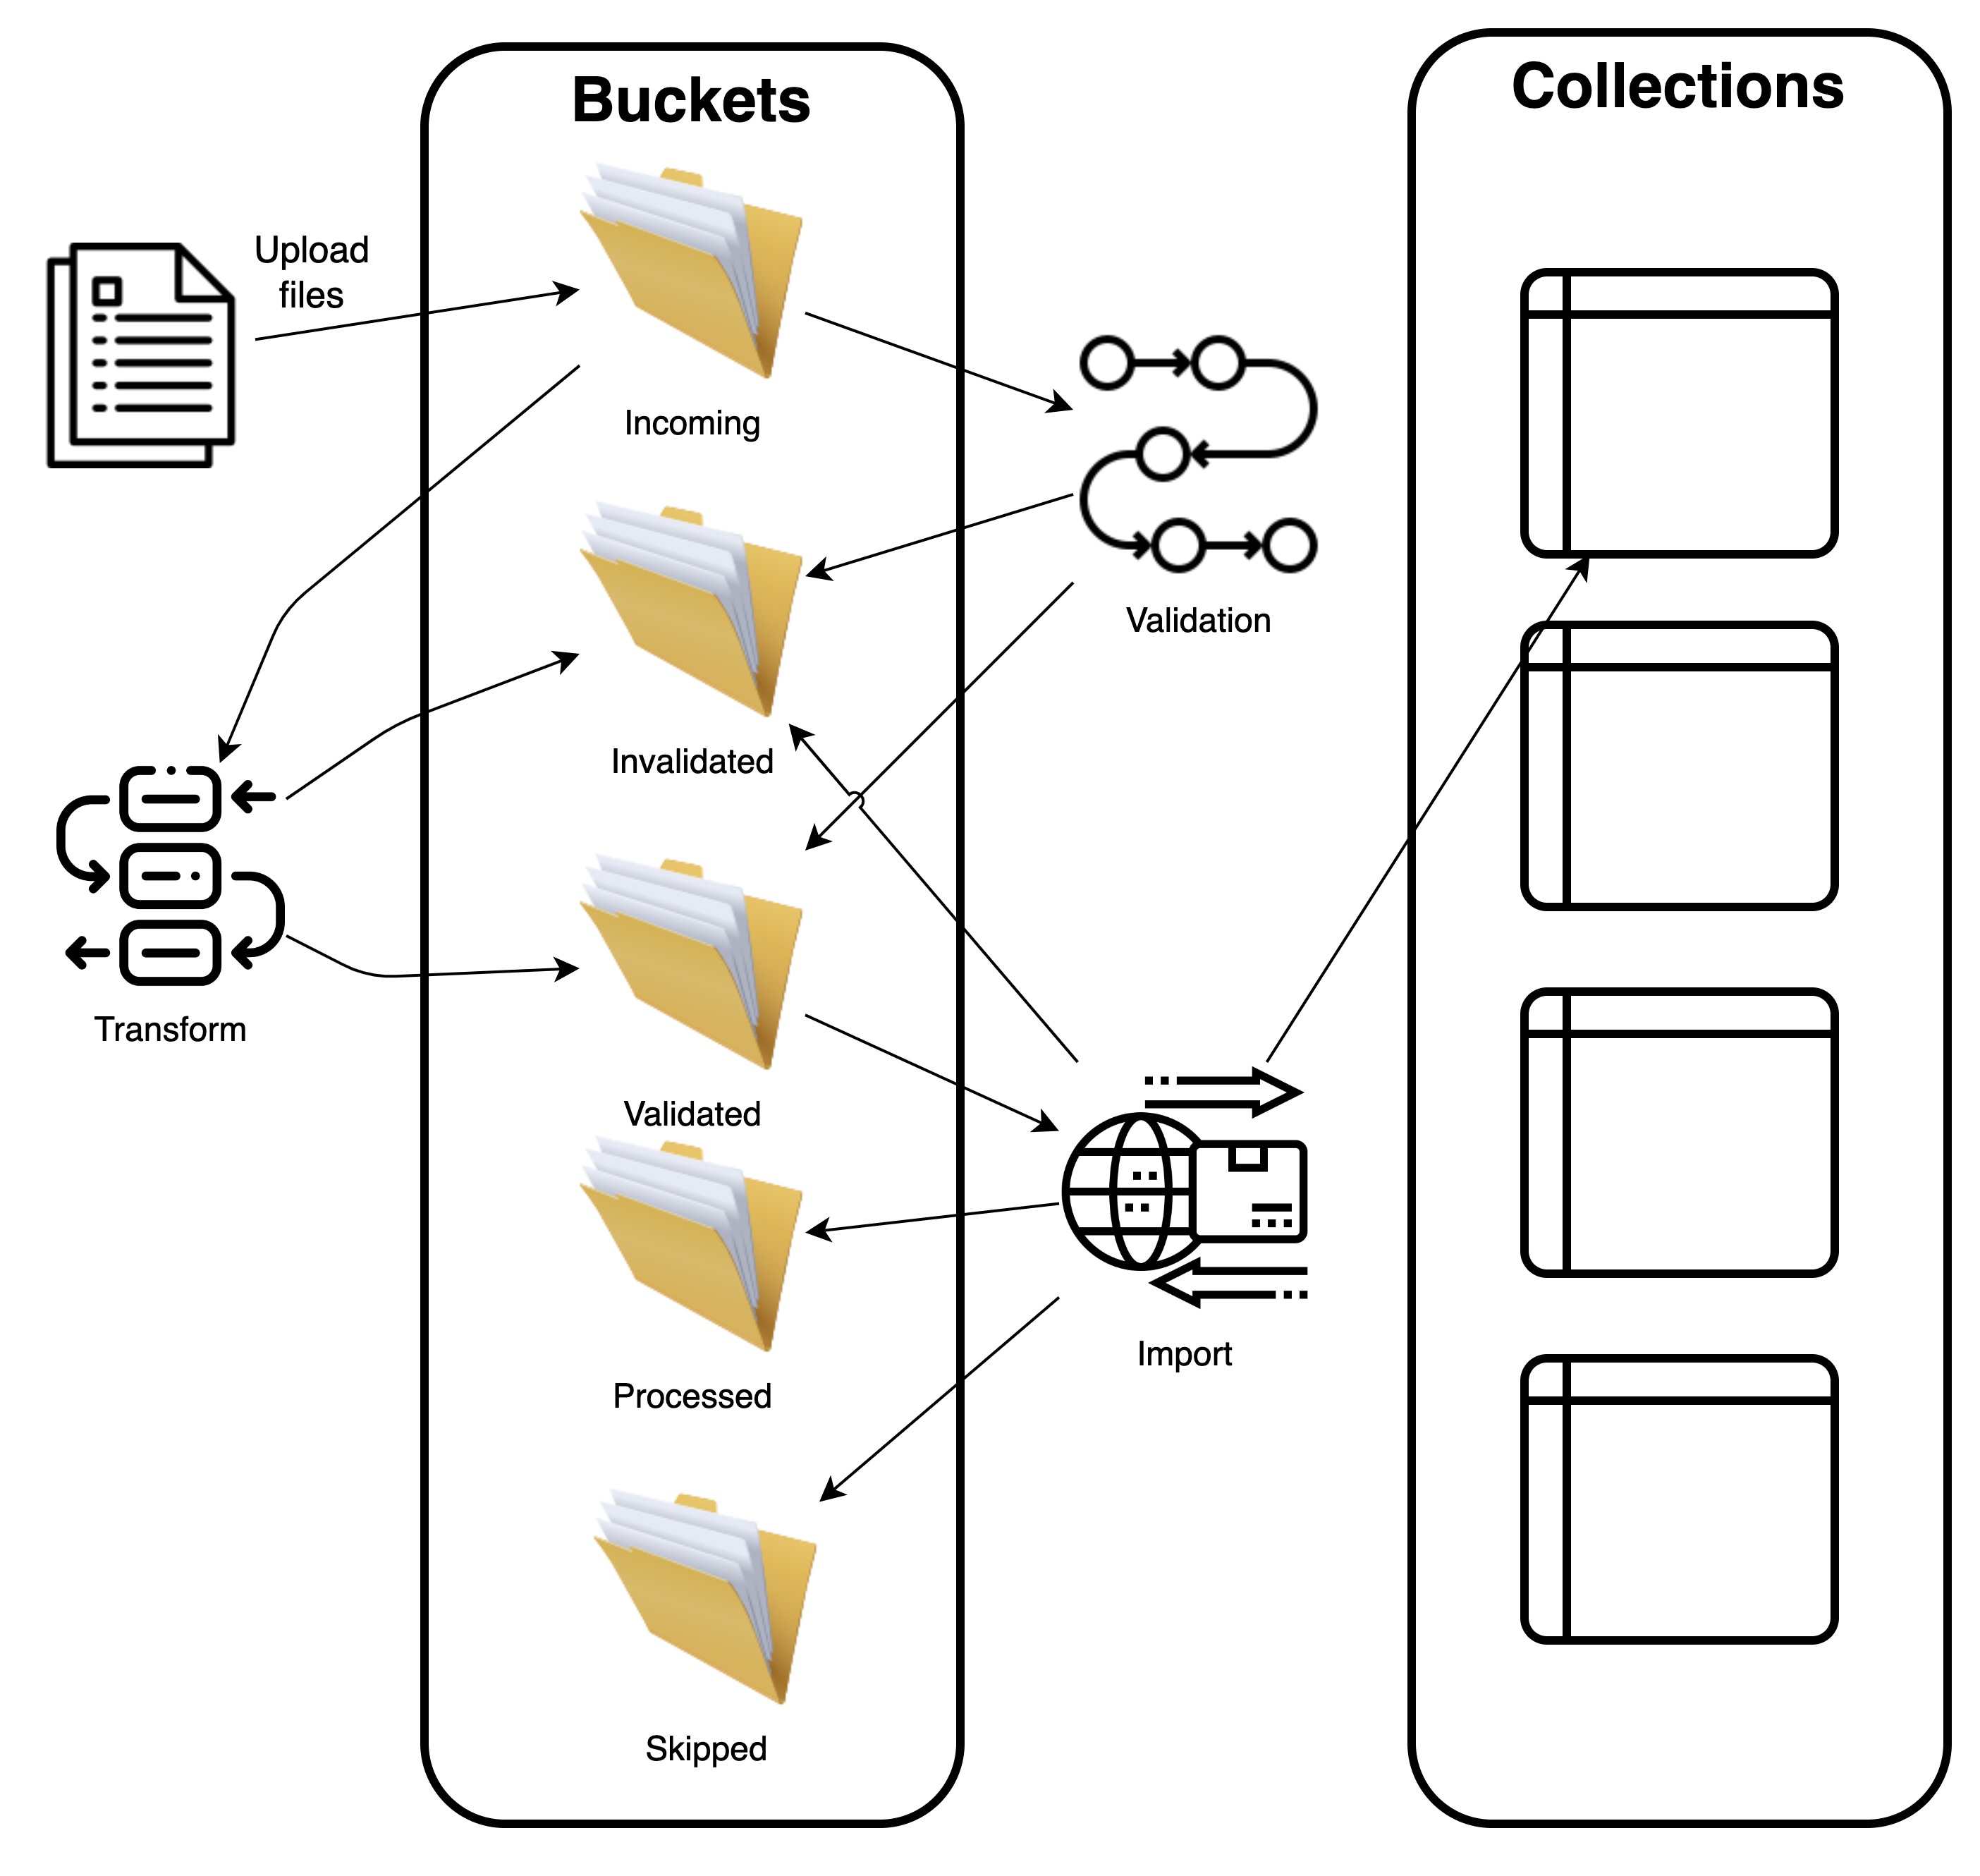
The following diagram shows how the Data File jobs fit into the overall Data File processing workflow.
Call Webservice Endpoint
| Job Type Code | Description |
|---|---|
| callWebserviceEndpoint | This job type is used to call a webservice endpoint. It can be used to call any webservice endpoint, including REST and GraphQL, using any HTTP method (e.g. POST, PATCH, DELETE, PUT, etc.) The job type supports GET, POST, PUT, and DELETE HTTP methods. |
Input Parameters
| Parameter | Required | Description |
|---|---|---|
| url | Yes | The URL of the webservice endpoint to call. |
| method | Yes | The HTTP method to use when calling the webservice endpoint. |
| headers | No | The headers to include in the request. |
| body | No | The body to include in the request. |
| searchParams | No | The query parameters to include in the request. |
Call DX Engine
| Job Type Code | Description |
|---|---|
| callDxEngine | This job type is used to call DX Engine. |
Input Parameters
| Parameter | Required | Description |
|---|---|---|
| templateCode | Yes | The DX Engine Template to invoke. |
| context | No | The context to include in the request. |
Process File With Webservice Endpoint
| Job Type Code | Description |
|---|---|
| processFileWithWebserviceEndpoint | The Job Type Process File With Webservice Endpoint is used to process a file and send the records to a webservice endpoint. The file can be any delimited file and JSON (array or newline-delimited). The job type supports sending batches of records to the webservice endpoint. |
Input Parameters
| Parameter | Required | Description |
|---|---|---|
| dataBucketCode | Yes | The data bucket code containing the file to process. |
| filename | Yes | The file that contains the records to process. This can be any delimited file and JSON (array or newline-delimited) |
| batchSize | No | The batch size to use. Defaults to 1. A batch of 3 will send an array of 3 JSON records to the webservice. |
| webserviceEndpoint | Yes | The webservice endpoint to call. This is an object. All of the webservice properties can contain a JavaScript expression (within backticks) that have reference to a variable called records which is the array of of records in the file. |
| webserviceEndpoint.url | Yes | The URL of the webservice endpoint to call. |
| webserviceEndpoint.method | Yes | The HTTP method to use when calling the webservice endpoint. |
| webserviceEndpoint.headers | No | The headers to include in the request. |
| webserviceEndpoint.body | No | The body to include in the request. |
| webserviceEndpoint.searchParams | No | The query parameters to include in the request. |
Example:
Take the following CSV file: people.csv
name,email
John Doe,john@email.com
Jane Doe,jane@email.com
Jim Doe,jim@example.com
Jill Doe,jill@example.com
The following parameters will send batches of two JSON records to a webservice endpoint.
{
  "dataBucketCode": "my-data-bucket",
  "filename": "people.csv",
  "batchSize": 2,
  "webserviceEndpoint": {
    "url": "https://my-webservice.com/api/v1/records",
    "method": "`records[0]method`",
    "headers": {
      "Content-Type": "application/json"
    },
    "body": {
      "data" : "`records`",
      "length": "`records.length`"
    }
  }
}
The body of each request will be:
{
  "data": [
    { "name": "John Doe", "email": "john@email.com" },
    { "name": "Jane Doe", "email": "jane@email.com" }
  ],
  "length": 2
}
followed by:
{
  "data": [
    { "name": "Jim Doe", "email": "jim@example.com" },
    { "name": "Jill Doe", "email": "jill@example.com" }
  ]
  "length": 2
}
Process File With DX Engine
| Job Type Code | Description |
|---|---|
| processFileWithDxEngine | The Job Type Process File With DX Engine is used to process a file and send the records to a DX Engine. The file can be any delimited file and JSON (array or newline-delimited). The job type supports sending batches of records to the DX Engine. |
Input Parameters
| Parameter | Required | Description |
|---|---|---|
| dataBucketCode | Yes | The data bucket code containing the file to process. |
| filename | Yes | The file that contains the records to process. This can be any delimited file and JSON (array or newline-delimited) |
| batchSize | No | The batch size to use. Defaults to 1. A batch of 3 will send an array of 3 JSON records to the webservice. |
| environmentCode | Yes | The DX Engine environment code to use. |
| token | Yes | The DX Engine token to use. |
| templateCode | Yes | The DX Engine template to invoke. |
| context | No | The context to include in the request. It defaults to {}. |
Both templateCode and context can contain a JavaScript expression (within backticks) that has a reference to a variable called records which is the array of records in the file. For example,
"templateCode": "`'template_' + records[0].name`"
or
"context": {
    "data": "`records[0]`"
}
Process Collection With Webservice Endpoint
| Job Type Code | Description |
|---|---|
| processCollectionWithWebserviceEndpoint | The Job Type Process Collection With Webservice Endpoint is used to process a DX Graph Collection and send the records to a webservice endpoint. The job type supports sending batches of records to a webservice endpoint. |
Input Parameters
| Parameter | Required | Description |
|---|---|---|
| collectionCode | Yes | The data bucket code containing the file to process. |
| filter | No | The filter to apply to the collection. |
| batchSize | No | The batch size to use. Defaults to 1. A batch of 3 will send an array of 3 JSON records to the webservice. |
| webserviceEndpoint | Yes | The webservice endpoint to call. This is an object. All of the webservice properties can contain a JavaScript expression (within backticks) that have reference to a variable called records which is the array of of records in the file. |
| webserviceEndpoint.url | Yes | The URL of the webservice endpoint to call. |
| webserviceEndpoint.method | Yes | The HTTP method to use when calling the webservice endpoint. |
| webserviceEndpoint.headers | No | The headers to include in the request. |
| webserviceEndpoint.body | No | The body to include in the request. |
| webserviceEndpoint.searchParams | No | The query parameters to include in the request. |
Process Collection With DX Engine
| Job Type Code | Description |
|---|---|
| processCollectionWithDxEngine | The Job Type Process Collection With DX Engine is used to process a DX Graph Collection and send the records to a DX Engine. The job type supports sending batches of records to the DX Engine. |
Input Parameters
| Parameter | Required | Description |
|---|---|---|
| collectionCode | Yes | The data bucket code containing the file to process. |
| filter | No | The filter to apply to the collection. |
| batchSize | No | The batch size to use. Defaults to 1. A batch of 3 will send an array of 3 JSON records to the webservice. |
| environmentCode | Yes | The DX Engine environment code to use. |
| token | Yes | The DX Engine token to use. |
| templateCode | Yes | The DX Engine template to invoke. This can contain a JavaScript expression (within backticks) that has a reference to a variable called records which is the array of batched records (based on batchSize) in the collection. |
| context | No | It defaults to {}. The context to include in the DX Engine request. This can contain a JavaScript expression (within backticks) that has a reference to a variable called records which is the array of batched records (based on batchSize) in the collection. |
Download Data From Webservice
This Job Type is covered here.
Export Collection To File
Collection data can be exported to a file in a Data Bucket. This mechanism is useful for exporting data to be consumed by another system such as a search engine, database, data warehouse, etc.
The Export Collection job exports every record from a Collection that matches a specified filter (if provided) into a file in a Data Bucket. Any transformation or schema errors are uploaded to an errors file in the same Data Bucket. More details on error files are here. Exported files are in line-delimited JSON format.
| Job Type Code | Description |
|---|---|
| exportCollection | The Job Type Export Collection is used to export data from a Collection into a file in a Data Bucket. |
Input Parameters
| Parameter | Required | Description |
|---|---|---|
| collectionCode | Yes | The Collection to export from. |
| targetBucketCode | Yes | The DX Graph Bucket that the Data File will be exported to. |
| filenamePattern | Yes | The name of the file that the data will be written to. You can use the placeholder {{timestamp}} to include the timestamp of the export request. Example: products_{{timestamp}}.jsonl would result in files that look like: products_20230514_131001.jsonl. See Filename Patterns for more information. |
| filter | No | A DX Graph filter that will be applied to the source records. If a filter is not provided, then all records will be exported. |
| recordLayoutConfig | No | If this is specified, the export of the records are in the Expanded Record Format. This defines what fields and relationships to return. You can see details here. If not specified, the records are exported as-is. |
| limit | No | The number that number of records that should be exported. If a limit is not provided, then all records will be exported. |
| transformers | No | An array of transformations applied to each source record in the collection. |
For examples on the use of filter, recordLayoutConfig, and limit, see Querying DX Graph Collections.
When specifying any transformers, you must keep in mind that the source record is in the Expanded Record Format. The transformers have access to Expanded Record Format functions
Upload Data to Azure Blob Storage
| Job Type Code | Description |
|---|---|
| uploadToAzureBlobStorage | The Job Type Upload Data to Azure Blob Storage is used to upload files into a storage container in Azure. |
Input Parameters
| Parameter | Required | Description |
|---|---|---|
| customerCode | Yes | The customer code of this instance. |
| azureConnectionString | Yes | The Azure blob storage connection string. |
| sourceBucketCode | Yes | Conscia bucket to look into. |
| filenamePattern | Yes | Groups files into a set of a files to be processed together. See File Name Patterns here. |
| azureContainerName | Yes | The Azure folder/container to upload files into. |
Orchestrate Jobs
| Job Type Code | Description |
|---|---|
orchestrateJobExecutions | The Orchestrate Job Executions job runs a set of other Jobs as a single Job. Each Job in the set is an execution, and the sequence defines which executions wait for which. Executions that do not depend on each other run in parallel, and an execution whose dependencies did not complete successfully is skipped. |
Each execution runs as a Job in its own right, with its own Job ID, and can be inspected with the usual Job endpoints. The orchestration Job completes once every execution has ended, and its result reports the outcome of each one.
To execute this job directly:
POST /_api/v1/job-types/orchestrateJobExecutions/_execute
Content-Type: application/json
X-Customer-Code: <customerCode>
Authorization: Bearer <apiKey>

{
  "params": {
    "executions": [
      {
        "executionCode": "importProducts",
        "executionType": "jobType",
        "name": "Import Products",
        "config": {
          "jobTypeCode": "importDataFiles",
          "params": {
            "incomingBucketCode": "incoming"
          }
        }
      },
      {
        "executionCode": "exportProducts",
        "executionType": "jobType",
        "name": "Export Products",
        "config": {
          "jobTypeCode": "exportCollectionToFile",
          "params": {
            "collectionCode": "products"
          }
        }
      },
      {
        "executionCode": "refreshEngine",
        "executionType": "jobType",
        "name": "Refresh Engine",
        "config": {
          "jobTypeCode": "callDxEngine",
          "params": {
            "templateCode": "product-feed"
          }
        }
      }
    ],
    "sequence": [
      { "executionCode": "exportProducts", "dependencies": ["importProducts"] },
      { "executionCode": "refreshEngine", "dependencies": ["importProducts"] }
    ]
  }
}
The call returns as soon as the orchestration Job has been queued:
{
  "jobId": "20261019-9f1c7a62-4c05-4f4a-8a21-2b0d7d6f1e3a"
}
The customer code and the Job ID are supplied by the platform, and the executions are run with the API Key of the caller. Do not include customerCode, jobId or apiKey in params — they are overwritten.
Input Parameters
| Parameter | Required | Description |
|---|---|---|
executions | Yes | The Jobs to run. At least one execution is required. The order of this array does not determine the order of execution — use sequence for that. |
executions[].executionCode | Yes | Identifies the execution within this orchestration. Must be unique, and is the key used by sequence and by the result. |
executions[].executionType | Yes | Options: jobType or jobDefinition. Determines which fields of config are used. |
executions[].name | No | A label for the execution. Returned in the result and in the Job messages; it does not affect execution. |
executions[].trigger | No | Default: true. When false, the execution is skipped and so is everything that depends on it. |
executions[].config | Yes | The Job to run. See the config rows below. |
executions[].config.jobTypeCode | Yes | Required when executionType is jobType. The Job Type to run. |
executions[].config.params | No | Used when executionType is jobType. The input parameters of that Job Type. |
executions[].config.jobDefinitionCode | Yes | Required when executionType is jobDefinition. The Job Definition to run. Its parameters cannot be overridden here — the Job Definition runs as configured. |
sequence | No | Default: []. The dependencies between executions. With no sequence, every execution starts at once. |
sequence[].executionCode | Yes | The execution that has to wait. Must match an executionCode in executions. |
sequence[].dependencies | No | Default: []. The executionCodes that must complete before this execution starts. Entries may be listed in any order, and an execution may appear in more than one sequence entry — its dependencies are combined. |
executionTimeout | No | Default: 1 day. How long to wait for any single execution to end before marking it as failed, as a duration (for example 30m, 2 hours, 1 day). |
Ordering Executions
An execution starts as soon as every execution it depends on has completed. Anything that can run at the same time does.
The sequence in the example above runs importProducts first, then starts exportProducts and refreshEngine together. If each of the three Jobs takes five minutes, the orchestration takes about ten minutes rather than fifteen.
To run the three Jobs strictly one after another, make each one depend on the previous:
{
  "sequence": [
    { "executionCode": "exportProducts", "dependencies": ["importProducts"] },
    { "executionCode": "refreshEngine", "dependencies": ["exportProducts"] }
  ]
}
An execution can depend on several others, in which case it waits for all of them — for the slowest, not for the first to finish. Given the executions importProducts, importOffers and exportCatalog, the two imports run in parallel and the export waits for both:
{
  "sequence": [
    { "executionCode": "exportCatalog", "dependencies": ["importProducts", "importOffers"] }
  ]
}
Every executionCode named in a sequence entry, including every dependency, has to be declared in executions.
Execution State
The result of the orchestration Job is an object keyed by executionCode, reporting what happened to each execution. Running the three Jobs strictly one after another, with exportProducts failing, gives:
{
  "importProducts": {
    "status": "COMPLETED",
    "name": "Import Products",
    "executionType": "jobType",
    "jobId": "20261019-cd7f5891-93af-4a8c-8bd9-96e30fcb2509",
    "startTime": "2026-10-19T14:22:02.550Z",
    "endTime": "2026-10-19T14:24:07.581Z",
    "result": { "recordsImported": 1402 }
  },
  "exportProducts": {
    "status": "FAILED",
    "name": "Export Products",
    "executionType": "jobType",
    "jobId": "20261019-c09e9070-7ace-475f-9026-6a20d07d7fff",
    "startTime": "2026-10-19T14:24:07.581Z",
    "endTime": "2026-10-19T14:24:09.618Z",
    "error": "Job Processing Error: Collection not found"
  },
  "refreshEngine": {
    "status": "SKIPPED",
    "name": "Refresh Engine",
    "executionType": "jobType",
    "jobId": "20261019-84b5f039-b832-4413-8b6c-a4319a3bb113",
    "startTime": null,
    "endTime": null,
    "reason": "Dependencies did not complete: exportProducts (FAILED)"
  }
}
| Field | Description |
|---|---|
status | The outcome of the execution. See the statuses below. |
name | The name given to the execution in the request. |
executionType | The executionType given to the execution in the request. |
jobId | The Job ID of the Job that was run for this execution. Assigned before the Job is queued, so it is reported even for executions that were skipped or could not be started. |
startTime | When the execution's Job was queued, in UTC. null if the execution was skipped. |
endTime | When the execution's Job ended, in UTC. null if the execution was skipped. |
result | The result of the execution's Job. Only present once the Job has ended. |
error | Why the execution failed. Only present on failed executions. |
reason | Why the execution was skipped. Only present on skipped executions. |
| Status | Description |
|---|---|
COMPLETED | The execution's Job ended successfully. |
FAILED | The execution's Job failed, could not be queued, or did not end within executionTimeout. |
SKIPPED | The execution was not triggered, or one of its dependencies did not complete. Its Job was never queued. |
PENDING | The execution has not started yet. Every execution carries this status in the ORCHESTRATION_STARTED message; it never appears in the result of a finished orchestration. |
Monitoring Progress
An orchestration logs a message as it starts and another as each execution ends, so progress can be followed without waiting for the whole Job:
GET /_api/v1/jobs/{jobId}/messages?limit=50
X-Customer-Code: <customerCode>
Authorization: Bearer <apiKey>
| Log Type | Description |
|---|---|
ORCHESTRATION_STARTED | Logged once, before any Job is queued. logData.executionState holds the starting state of every execution, which is the quickest way to collect the Job IDs that the orchestration is about to use. |
EXECUTION_COMPLETED | Logged once per execution, as it ends. logData.executionCode names the execution and logData.executionState holds its final state. |
EXECUTION_COMPLETED is logged when an execution settles, whichever way it settled — including executions that failed and executions that were skipped. Read logData.executionState.status for the actual outcome rather than relying on the log type.
Messages are returned in the order they were logged, up to limit, which defaults to 10. An orchestration of ten or more executions needs a higher limit for the later messages to appear.
GET /_api/v1/jobs/{jobId}/status-details reports the status transitions of the orchestration Job itself (queued, started, completed) but does not carry the execution state.
Skipping Executions
An execution is skipped, and its Job is never queued, when either:
- its
triggerisfalse—reasonisNot triggered; or - one of its dependencies did not reach
COMPLETED—reasonnames the dependency and its status, for exampleDependencies did not complete: exportProducts (FAILED).
Skipping cascades. If an execution is skipped, everything that depends on it is skipped too, and the reason of each names the execution directly above it in the chain.
A failed or skipped execution never stalls the rest of the orchestration: branches that do not depend on it carry on, and the orchestration Job ends once every branch has settled.
An orchestrated Job reports its failure to the orchestration on its first failed attempt, while the Job queue is configured to retry a failed Job up to three times. An execution can therefore be reported as FAILED while its Job is still being retried, and a later attempt that succeeds will not change the reported outcome.
Errors
The executions and the sequence are validated together before any Job is queued. If the validation fails, nothing is run and the orchestration Job fails with one of the following:
| Error Type | Description |
|---|---|
DUPLICATE_EXECUTION_CODE | Two executions share an executionCode. |
UNSUPPORTED_EXECUTION_TYPE | An execution has an executionType other than jobType or jobDefinition. |
UNKNOWN_EXECUTION_CODE | A sequence entry names an executionCode that is not in executions. |
UNKNOWN_DEPENDENCY | A dependency names an executionCode that is not in executions. |
SELF_DEPENDENCY | An execution lists itself as one of its dependencies. |
CIRCULAR_DEPENDENCY | The dependencies form a cycle, so no execution could ever start. The error names the executions involved. |
Because the validation happens inside the Job, _execute still returns 200 and a jobId for an invalid request — the orchestration Job then fails without retrying, and the error is read from the Job status. An execution that refers to a Job Type or Job Definition that does not exist is not caught by this validation: the orchestration starts, that execution fails with the error from the Job that could not be queued, and the executions that depend on it are skipped.
Apply Taxonomy
| Job Type Code | Description |
|---|---|
applyTaxonomy | The Apply Taxonomy job applies a Taxonomy collection to its Target collection |
To execute this job directly:
POST /_api/v1/job-types/applyTaxonomy/_execute
Content-Type: application/json
X-Customer-Code: <customerCode>
Authorization: Bearer <apiKey>

{
  "params": {
    "taxonomyCollectionCode": "product-category",
    "filter": {
      "$eq": {
        "field": "group",
        "value": "211"
      }
    }
  }
}
Input Parameters
| Parameter | Required | Description |
|---|---|---|
taxonomyCollectionCode | Yes | The Taxonomy Collection to process. |
filter | No | This filter specifies which Taxonomy records are applied to the target Collection. When no filter is specified, all Taxonomy records are applied. |
Materialize Shadow Fields
| Job Type Code | Description |
|---|---|
materializeShadowFields |
To execute this job directly:
POST /_api/v1/job-types/materializeShadowFields/_execute
Content-Type: application/json
X-Customer-Code: <customerCode>
Authorization: Bearer <apiKey>

{
  "params": {
    "collectionCode": "product",
    "filter": {
      "$eq": {
        "field": "brand_id",
        "value": "acme"
      }
    }
  }
}
Input Parameters
| Parameter | Required | Description |
|---|---|---|
collectionCode | Yes | The Collection for which the Shadow Fields should be materialized. |
filter | No | This filter specifies which records inthe Collection that should have their Shadow Field materialized. When no filter is specified, all records are processed. |